Server Maintenance for Small Businesses: A Practical Checklist
Use this small-business server maintenance checklist to plan updates, backups, monitoring, access reviews, capacity checks, recovery testing, and lifecycle decisions.
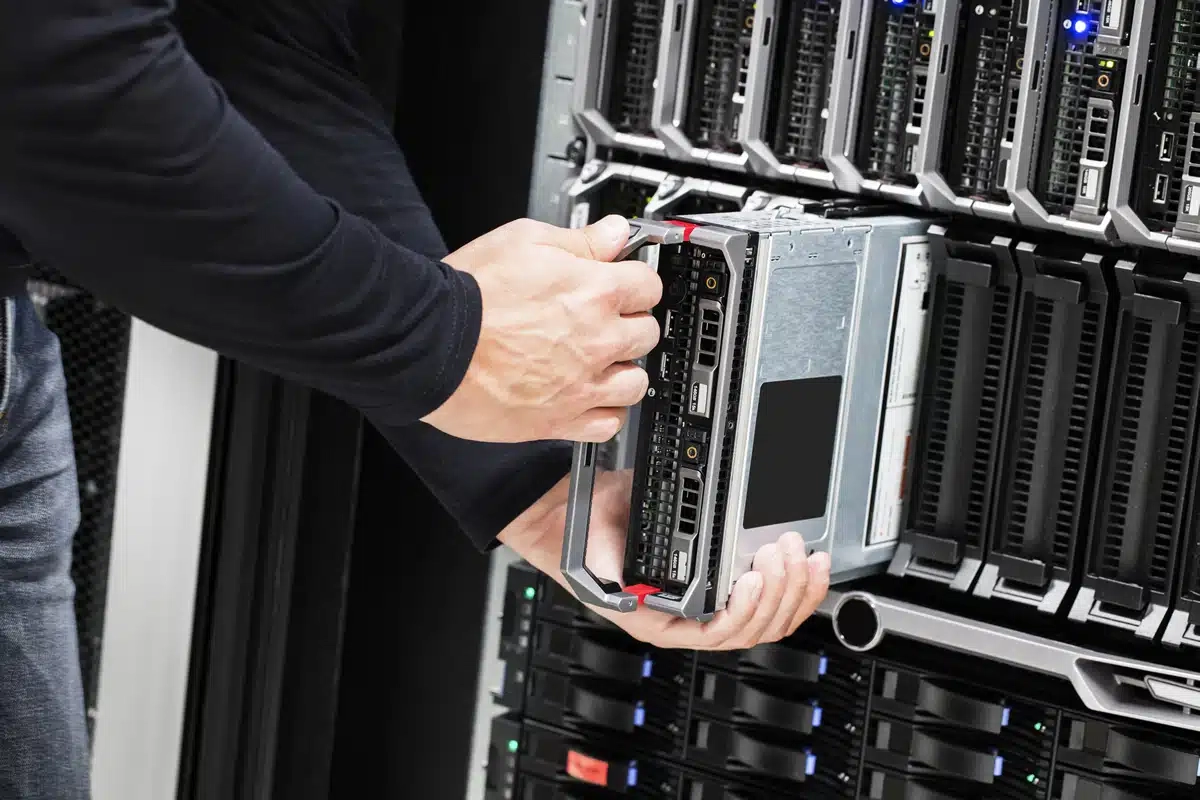
A server can look healthy right up until a small problem becomes an outage.
Storage fills gradually. A backup job stops completing. An administrator account belongs to someone who no longer needs it. Updates are postponed because nobody wants to interrupt the workday. A certificate approaches expiration. An old server keeps running even though support and recovery options are getting harder to manage.
That is why server maintenance should be treated as an operating process, not a repair activity that starts after something breaks.
SMART Solutions provides Computer, Server & Device Support for business technology, including maintenance, troubleshooting, configuration, remote support, and data-protection planning.
SMART takeaway
Maintain the service, not just the box.
A useful maintenance routine tracks updates, backups, capacity, logs, access, dependencies, support status, and recovery readiness so problems can be handled before they become emergencies.
Quick answer: what should server maintenance include?
A practical small-business server maintenance process should review:
- Operating-system, application, firmware, and security updates
- Backup completion and periodic recovery testing
- Disk, storage, memory, CPU, and capacity trends
- System, application, security, and backup logs
- Administrator, service, and remote-access accounts
- Security and monitoring agent status
- Power, UPS, network, and environmental dependencies
- Certificates, licenses, warranties, and vendor support dates
- Change documentation and unresolved issues
- Lifecycle and replacement planning
NIST describes patch management as preventive maintenance for technology. CISA also recommends logging and monitoring business systems so organizations can identify abnormal activity sooner.
Sources: NIST SP 800-40 Rev. 4 and CISA — Use Logging on Business Systems.
1. Document what the server actually supports
Maintenance starts with context. Record the server’s role, owner, operating system, applications, dependencies, backup method, maintenance window, support status, and recovery priority.
A file server, directory server, database server, application server, virtualization host, and backup server do not necessarily have the same outage tolerance or maintenance requirements.
Our IT asset inventory guide provides a framework for connecting technology assets with owners, purpose, lifecycle status, and recovery priority.
2. Review patches and vendor advisories
Do not reduce maintenance to “install every update immediately.” A better process is to identify, prioritize, test when practical, install, and verify updates.
Review operating-system patches, server applications, hypervisors, backup agents, security agents, management tools, and relevant firmware. Ask whether a restart or outage window is required and how the team will verify that business services came back correctly.
CISA’s Known Exploited Vulnerabilities Catalog can help prioritize vulnerabilities known to be exploited in the wild.
For the broader workflow, see our small-business patch management guide.
3. Verify backups instead of assuming they work
A successful backup notification is useful, but it does not prove the business can restore a service.
Check whether scheduled jobs completed, whether the right volumes and applications are protected, whether failed jobs trigger alerts, whether recovery credentials still work, and whether a recent controlled restore has been tested.
The key question is: Could the business recover the required service with the people, credentials, documentation, and backup data available today?
Our business backup and recovery testing guide goes deeper into recovery priorities, credentials, dependencies, and restore testing.
4. Watch capacity trends before they become emergencies
Review free disk space, database growth, log growth, backup repository usage, CPU and memory pressure, and virtual-machine host capacity where applicable.
A single high reading does not automatically justify replacement. Trends matter. Define thresholds that trigger investigation before the system reaches a critical condition.
5. Review logs and monitoring alerts
CISA recommends enabling logging on important business systems and using monitoring to identify unusual behavior.
Server maintenance should review significant events such as service crashes, unexpected restarts, authentication failures, privilege changes, backup failures, storage warnings, hardware alerts, application errors, and repeated network failures.
If an alert has been ignored for months, either the underlying condition needs attention or the alerting rule needs improvement.
6. Reconcile administrator and remote access
Check who has local, domain, cloud, or remote administrative rights. Review service accounts, former employees, vendor accounts, remote-management tools, recovery identities, and MFA coverage where supported.
Routine work should not automatically require elevated privileges. Access should match current responsibilities.
Our user access review checklist covers stale accounts, privileged access, vendor identities, shared accounts, recovery methods, and role changes.
7. Confirm management and security agents are reporting
Antivirus, endpoint protection, monitoring, remote-management, inventory, and backup tools cannot help if their agents are stopped, disconnected, or assigned to the wrong tenant.
Confirm that critical agents are running, checking in, receiving policies and updates, and not reporting unresolved errors. Pay special attention after operating-system upgrades, restores, migrations, or network changes.
8. Inspect the infrastructure around the server
A healthy server can still be vulnerable to surrounding failures.
Depending on the environment, review UPS status, power, cooling, switch ports, storage appliances, hypervisor hosts, DNS, directory services, firewall dependencies, internet circuits, and remote sites.
If connectivity is critical, our business internet redundancy guide explains why continuity planning has to include the path to the service, not just the server itself.
9. Track certificates, licenses, warranties, and support dates
Not every outage starts with hardware failure. Services can stop because a certificate expires, a subscription lapses, or software reaches end of support.
Keep a forward-looking list of certificate expiration, software renewals, hardware warranty dates, operating-system support dates, application support dates, and replacement lead times.
The goal is to turn lifecycle events into planned projects instead of surprise emergencies.
10. Use an approved maintenance window and rollback plan
Before a change that may interrupt operations, document what will change, who approves it, which services may be affected, what backup or snapshot exists, how success will be tested, and what conditions trigger rollback.
Afterward, test the service users actually need — authentication, file access, a business application, database connectivity, scheduled jobs, or remote access — rather than only checking whether the server responds to a ping.
11. Keep a maintenance record
Record the date, person performing the work, updates installed, backup checks, alerts reviewed, capacity observations, access changes, configuration changes, problems found, follow-up owner, and target completion date.
That record becomes valuable when someone later asks, “What changed before this problem started?”
How often should server maintenance happen?
Different checks need different cadences.
The right cadence depends on business criticality, operating hours, vendor requirements, and the consequences of an outage.
Server maintenance FAQ
Is server maintenance the same as patch management?
No. Patch management is part of maintenance, but maintenance also covers backups, recovery readiness, capacity, monitoring, access, dependencies, documentation, and lifecycle planning.
Should all server updates be automatic?
Automation can help, but important servers still need a process for prioritization, maintenance windows, verification, and rollback. Automation should not remove accountability.
What is the biggest server-maintenance mistake?
Waiting until something fails. Preventive maintenance is most valuable when it finds a backup, capacity, update, access, or lifecycle problem while there is still time to plan.
Can SMART Solutions help maintain business servers?
Yes. SMART Solutions’ Computer, Server & Device Support offering includes maintenance, troubleshooting, configuration, remote support, and data-protection planning for business technology.
Authoritative sources
- NIST SP 800-40 Rev. 4 — Guide to Enterprise Patch Management Planning
- CISA — Known Exploited Vulnerabilities Catalog
- CISA — Use Logging on Business Systems
- CISA — Small and Medium-Sized Business Resources
Make server maintenance predictable
A small-business server should not depend on memory or emergency troubleshooting. Create a repeatable maintenance schedule, verify backups, watch capacity, review access, document changes, and plan replacement before support disappears.
If you want help building that process, explore Computer, Server & Device Support or contact SMART Solutions.